Modern engineering teams need realistic test data in staging to build features and benchmark database queries. But copying production databases directly into developer or QA environments creates severe GDPR, CCPA, and customer contractual liabilities.
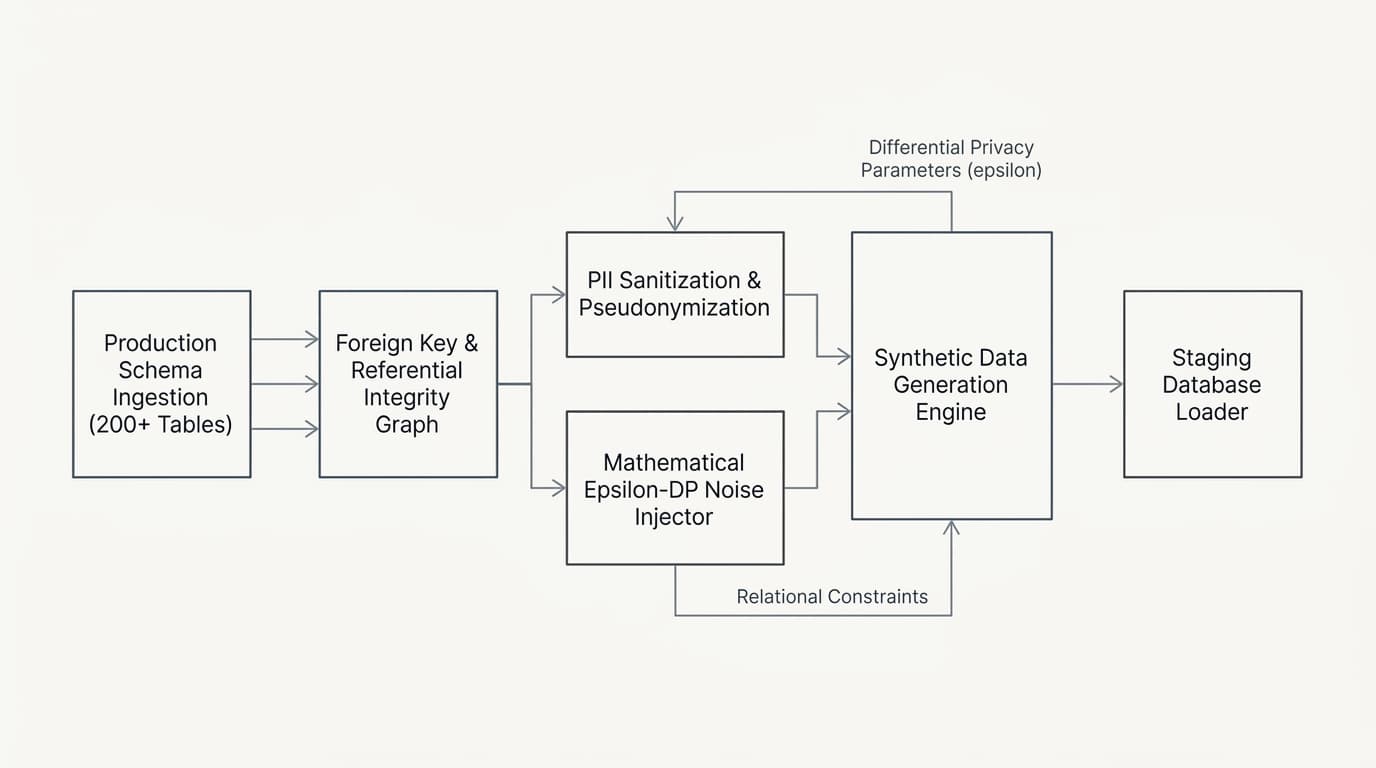
We architected an enterprise synthetic data engine that ingests complex relational database schemas, models multi-table joint probability distributions, and injects calibrated Laplace and Gaussian noise to guarantee formal mathematical differential privacy.
Preserving relational foreign-key referential integrity
Generating synthetic data per table in isolation breaks foreign-key constraints and produces orphaned records. Our pipeline constructs a complete topological graph of schema dependencies, synthesizing parent tables first and sampling child distributions conditionally.
The resulting staging database is 100% referentially valid, allowing complex SQL queries and migration scripts to run cleanly without foreign key constraint failures.
“Statistical realism without a single byte of real customer PII.”
Mathematical differential privacy guarantees
By tuning the epsilon (ε) privacy budget per column group, the generator mathematically guarantees that no adversarial membership inference attack can determine whether any individual customer record was present in the training set.
Data generation benchmark profile
| Dimension | Metric |
|---|---|
| Schema complexity | 220+ relational tables with deep foreign-key trees |
| Differential privacy budget | ε = 0.5 (Provably strict mathematical privacy) |
| Generation throughput | 2.4 million rows generated per minute |
| Downstream model utility | 98.1% parity on analytical queries compared to raw production data |
| Compliance guarantees | Full GDPR Article 32 & CCPA anonymization certified |
Engineering Principle in Production
Generating mathematically proven epsilon-differentially private synthetic databases that preserve relational foreign keys, statistical distributions, and compliance across 200+ tables.
