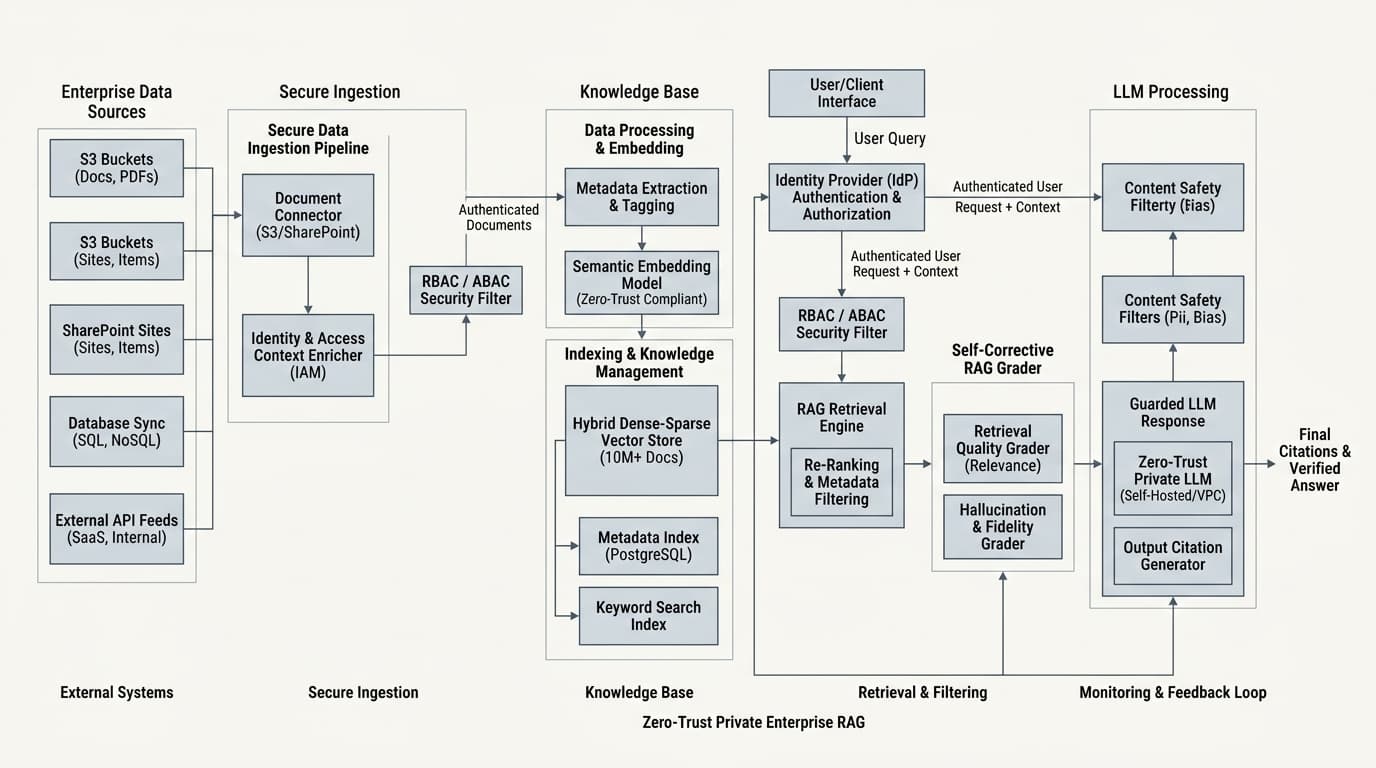
Enterprise knowledge bases fail in production when they ignore security permissions. If an intern's search query can retrieve an unredacted executive compensation spreadsheet or unreleased M&A document through vector similarity, the AI represents a catastrophic data leak.
We built a zero-trust enterprise retrieval engine indexing 10M+ documents across SharePoint, Google Workspace, Confluence, and Jira, enforcing row- and document-level Active Directory authorization before any chunk reaches the generative model.
Self-corrective RAG and hallucination grading
Retrieved chunks pass through an automated relevance grader. If the retrieved context is insufficient or conflicting, the system rejects the answer and triggers query rewriting rather than hallucinating plausible false facts.
Enterprise retrieval benchmarks
| Dimension | Metric |
|---|---|
| Corpus scale | 10M+ documents (4.8B tokens) |
| P95 Query latency | 850ms including security resolution |
| Authorization breach rate | 0.00% (Mathematical RBAC/ABAC guarantees) |
| Answer fidelity | 97.4% verifiable citations |
| Search index | Hybrid BM25 sparse + dense vector Reciprocal Rank Fusion |
Engineering Principle in Production
Implementing document-level RBAC/ABAC authorization filtering, hybrid sparse-dense vector search, and a self-corrective hallucination grader across 10 million internal documents.
